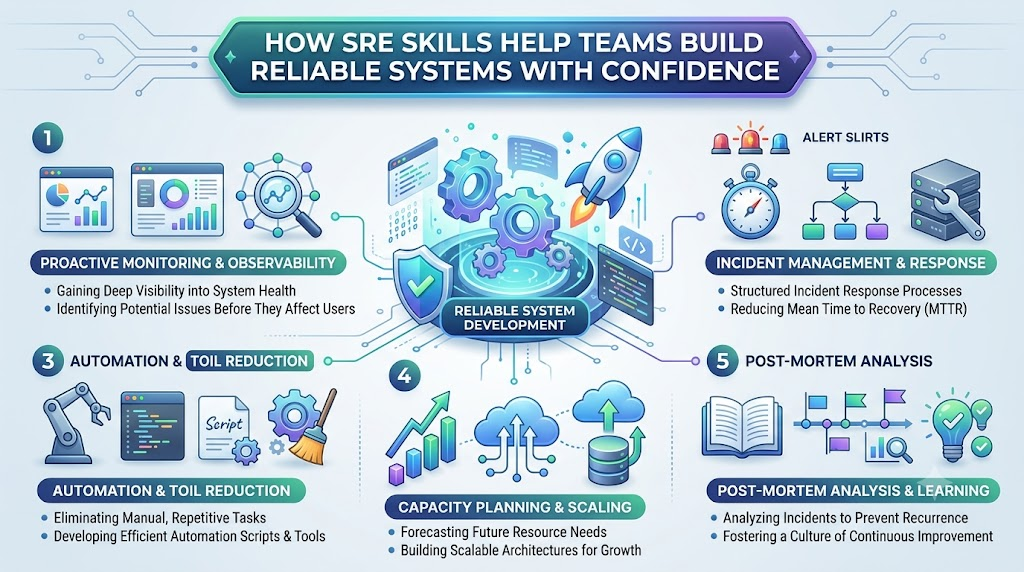
Introduction
Modern apps must work well every day. Users expect fast and steady services.
This is where Site Reliability Engineering, or SRE, can help. SRE joins software skills with system work.
An SRE Engineer helps keep services safe and reliable. They also find ways to reduce manual work.
SRESchool.in focuses on skills for this kind of work. Its learning path covers cloud systems, automation, monitoring, and reliability.
SRE Training can help beginners learn these skills step by step. An SRE Course can also help learners understand real system tasks.
The goal is simple. Build systems that work well and recover fast.
What Does SRE Mean?
SRE means Site Reliability Engineering. It is a way to manage software systems.
SRE teams care about system health. They also care about speed, safety, and user needs.
An SRE does not only watch servers. They also write code and set up tools.
For example, an SRE may automate a daily task. This saves time and can reduce human errors.
SRE also uses clear goals. These goals help teams know if a service works well.
Three common terms help explain these goals:
| Term | Simple meaning |
|---|---|
| SLI | A measure of service health |
| SLO | A target for service health |
| SLA | A service promise or agreement |
| Error budget | The allowed amount of failure |
An SLI may track how fast a website responds. An SLO may set a target for that speed.
An SLA can define what users should receive. An error budget shows how much failure a team can accept.
These ideas help teams make better choices.
Why Reliability Matters
A small system issue can affect many users. A slow app can also hurt user trust.
Reliable systems reduce these risks. They also help teams respond to problems faster.
SRE Best Practices can help teams plan for failures. They can also help teams learn from past incidents.
Key Skills Every SRE Engineer Needs
SRE work needs many skills. But beginners do not need to learn everything at once.
First, learn basic Linux and networking. These skills help you understand servers and system traffic.
Next, learn cloud basics. Cloud systems often need careful setup and regular checks.
Coding also matters. Python, Go, and similar tools can help with automation.
Automation means making a task run with less manual work. For example, a script can check a service every few minutes.
Monitoring is another key skill. It helps teams spot issues before they grow.
Observability goes one step further. It helps teams understand why a system behaves in a certain way.
Tools Used in SRE Work
SRE Tools help teams monitor, test, deploy, and fix systems.
Common tool groups include:
- Monitoring tools
- Logging tools
- Alerting tools
- Cloud platforms
- Container tools
- Infrastructure tools
- Deployment tools
- Incident tools
Kubernetes can help manage containers. Terraform can help manage cloud resources.
Monitoring tools can show system health. Log tools can help teams find error details.
No tool can solve every problem. The right tool depends on the system and team.
Automation Saves Time
Manual work can take many hours. It can also cause mistakes when repeated often.
SRE teams look for tasks they can automate. They may automate tests, alerts, reports, or system checks.
Good automation should be easy to understand. It should also be safe to run.
This makes automation an important SRE skill.
How SRE Teams Handle System Problems
System problems are part of production work. Even well-built systems can fail.
SRE teams prepare for these events. They use alerts, runbooks, and incident plans.
An alert tells a team that something needs attention. A runbook gives clear steps for common problems.
During an incident, teams first focus on the user impact. They then work to restore the service.
After recovery, the team reviews the event. This helps them find ways to prevent repeat issues.
A Simple Incident Process
A basic incident process can look like this:
- Detect the problem.
- Check the user impact.
- Find the likely cause.
- Restore the service.
- Check system health.
- Review what happened.
- Improve the system.
The process may change by team. The main goal stays the same.
Teams should also learn from incidents. They should avoid blame and focus on system improvement.
Monitoring and Observability
Monitoring answers a simple question. “Is the system working?”
Observability helps answer another question. “Why is the system acting this way?”
For example, a monitor may show high error rates. Logs may then show where those errors started.
Metrics, logs, and traces can work together. They give teams more clues during system problems.
Good alerts should also be useful. Too many alerts can make real issues harder to notice.
Learning SRE Step by Step
SRE can seem large at first. A clear learning path can make it easier.
Start with Linux, networking, and basic coding. Then learn cloud and DevOps concepts.
Next, study monitoring and observability. After that, learn containers and Kubernetes.
Then study SLOs, SLIs, error budgets, and incident response.
A simple learning path can look like this:
| Learning stage | Main focus |
|---|---|
| Beginner | Linux, networking, coding |
| Core | Cloud, DevOps, automation |
| Reliability | SLI, SLO, SLA, error budgets |
| Production | Monitoring, alerts, incidents |
| Advanced | Kubernetes, scaling, automation |
Practice matters at every stage. Small projects can help you understand each skill.
How an SRE Course Can Help
An SRE Course can give learners a clear learning path. It can group related topics into useful steps.
SRE Training can also include practice tasks. These tasks can help learners connect theory with real system work.
An SRE Tutorial can help with one topic at a time. This works well when learners need quick explanations.
SRESchool.in covers many areas linked to SRE work. Learners can use such resources to build their knowledge step by step.
SRE Training and Certification
SRE Training can help learners understand reliability work. It can also build skills in cloud systems, automation, and monitoring.
SRE Certification can show that a learner has studied key concepts. However, a certificate is only one part of skill building.
Practical work still matters. Learners should practice system checks, alerts, scripts, and incident tasks.
Site Reliability Engineering Training can also help working teams. Teams can learn shared methods for system health and incident work.
Site Reliability Engineering Certification may suit people who want a structured learning goal. Learners should still focus on real skills.
SRE Training in India
SRE Training in India can support learners from many technical backgrounds. Some may come from software development.
Others may come from cloud, DevOps, testing, or system administration.
A good learning plan should match the learner’s current skills. Beginners can start with basic system concepts.
Experienced professionals can move faster into cloud reliability and automation.
Frequently Asked Questions About SRESchool
1. What is SRE?
SRE means Site Reliability Engineering. It combines software and system work. SRE teams aim to keep services reliable and easy to manage. They use automation, monitoring, and clear reliability goals. They also study system problems and improve services after incidents.
2. What does an SRE Engineer do?
An SRE Engineer helps keep software systems reliable. They may write code, monitor services, manage cloud systems, and fix problems. They also automate repeated tasks. Their work can reduce manual effort and help teams respond to incidents faster.
3. What is SRE Training?
SRE Training teaches the main skills used in reliability work. It can cover monitoring, automation, cloud systems, incidents, and SLOs. It may also cover tools used in production systems. Good training should include both basic ideas and practical tasks.
4. What is an SRE Course?
An SRE Course gives learners a planned way to study SRE. It can start with basic system skills and move toward advanced topics. Course topics may include cloud, Kubernetes, monitoring, automation, and incident response.
5. What is SRE Certification?
SRE Certification confirms that a learner has completed a certification process. The exact topics depend on the program. Certification can support structured learning. However, learners should also build practical skills through projects and practice.
6. What are SRE Tools?
SRE Tools help teams manage reliable systems. They can support monitoring, logging, alerts, cloud work, deployment, and automation. Common tools include Kubernetes and Terraform. Teams choose tools based on their systems and daily needs.
7. What is an SLO?
An SLO is a reliability goal. It tells a team how well a service should work. For example, a team may set a target for service uptime. SLOs help teams focus on user needs and system health.
8. What is an error budget?
An error budget is the amount of failure a team can allow. It comes from the team’s reliability goal. If a service has many failures, the team may slow risky changes. This helps balance new work with system reliability.
9. Can beginners learn SRE?
Yes, beginners can learn SRE step by step. Start with Linux, networking, and basic coding. Then learn cloud, monitoring, and automation. After that, study SLOs, incidents, and tools. Practice can make each topic easier to understand.
10. How can SRESchool.in help learners?
SRESchool.in focuses on SRE and related technical skills. Its learning resources cover cloud, automation, monitoring, DevOps, and reliability. Learners can study core ideas and explore practical SRE topics. The content can support both beginners and working professionals.
Final Thoughts
SRE helps teams build and run reliable systems. It uses software, cloud skills, automation, and monitoring.
The field may seem large at first. A simple learning path can make it easier.
Start with basic system skills. Then learn cloud, automation, and monitoring.
Next, study SLOs, incidents, and observability. Practice these skills with small projects.
SRE Training and an SRE Course can provide structure. SRESchool.in can also support learning with SRE-focused resources.
The key lesson is simple. Good SRE work helps systems stay useful, stable, and easier to manage.
Leave a Reply